AI Playing Games on Its Own Is Becoming Part of Games — GPUs Face a New Kind of Demand#
Zi Xing | August 10, 2026
Hello everyone, Zi Xing here. Today we’re not talking about any particular card — we’re talking about a trend that is changing the definition of the “graphics card”: AI is no longer hiding in the game-development toolchain writing code and touching up textures. It is starting to enter the games themselves — as opponents that actually play, testers that actually run, and maybe even your teammate.
For ordinary players, this trend matters far more than “another new feature.” It moves a workload that used to belong only to data centers and dev machine rooms quietly onto the graphics card sitting on your desk. Below I’ll break it into pieces: how to read it, and how it should steer the direction of your spending.
The Core Shift: AI Goes From “Tool” to “Player”#
Over the past two years, AI’s role in the games industry mostly stayed on the development side: procedural generation, asset assistance, translation and localization. The new story of 2026 is that AI is starting to appear as a “player entity” in two very different settings — inside the game and in development testing.
The two lines share one trait: both need to consume compute continuously, in places players never see. We used to discuss graphics cards with one default question — “how fast can it render this frame?” Now there’s a second variable: “it also has to keep feeding a thinking character.”
In-Game: Proactive NPCs and AI Teammates#
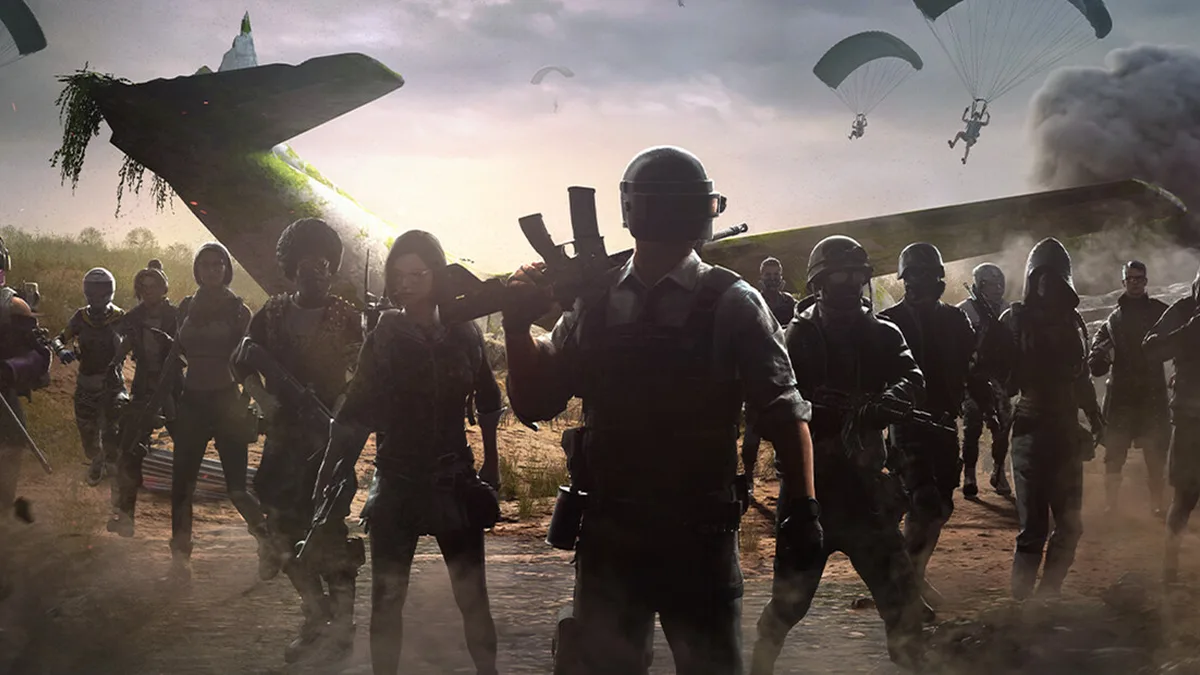
The most representative deployment is NVIDIA’s ACE (Avatar Cloud Engine) platform. Early on it was a tech demo stapled to new-product keynotes; now it runs inside officially shipped games: in PUBG: BATTLEGROUNDS, AI characters carry dialogue and tactical decision-making; in inZOI, autonomous characters respond in character from their own “small model” memory without any player input — no longer scripted puppets walking fixed patrol routes.
The common thread in these features: behind every autonomous NPC, a small language model or decision model is running continuously. Players see “smarter characters”; for hardware, it means that beyond rendering frames, the GPU carries a persistent inference load.
The key difference here is the shape of the load. Traditional rendering is “bursty”: the more complex the scene and the flashier the image, the hungrier the frame — but the compute demand fluctuates between frames. AI inference tends to be “continuous”: as long as the character is thinking, the model is running, whether it’s idling quietly or in a firefight. Stacking both on the same chip creates thermal and power-management pressures different from anything before.
Push the view further and the VRAM demand from these autonomous characters isn’t just “a bit more.” Model weights, context memory, and dialogue state all need to stay resident in VRAM; once they get swapped out or compressed, the character’s “memory” can blank out — conversations stop making sense and behavior contradicts itself. VRAM capacity is quietly shifting from a metric of “can it fit the textures” to one of “can it host a character’s brain.”
On the Dev Side: AI Test Agents Hunting Bugs in Players’ Stead#
Another quieter but more certain trend is AI-driven automated testing. Traditional game QA relies on people grinding through maps and on player community feedback — time-consuming, with blind spots in coverage. More and more teams are now trying reinforcement-learning agents to simulate different player styles, playing around the clock to dig up the corners human testers “can’t be bothered to visit” or “forgot existed.”
The core advantage of this kind of agent is that it has no natural “path dependency.” Human testers tend to walk the routes they know over and over, while AI agents can systematically enumerate interaction combinations and even “predict” potential crash points before a player loses their temper. For developers, that shifts part of the QA burden onto compute ahead of time — pulling compute demand forward into the pre-launch development stage.
To be clear: these agents are not simply “letting AI farm scores.” Score-farming pursues efficiency and reward maximization; test agents pursue coverage and anomaly discovery — the two reward functions are designed completely differently. A competent test agent must be able to actively try the operations that “look like they’ll fail,” rather than repeat already-validated success paths.
Seen through the cost structure, this also pulls large amounts of compute demand forward to the eve of launch. Compute used to go mainly toward “drawing the game”; now part of it goes toward “making the game understood and verified.” The two occupy different positions, but both point at the same trend: AI’s involvement is redistributing the games industry’s demand for compute.
For Player Hardware: Three New Compute Bills#
Put the two lines together and AI’s impact on the consumer GPU splits into three:
| Demand Source | Scenario | Direct Hardware Impact | Key Load |
|---|---|---|---|
| Autonomous NPCs / AI teammates | Turn-off decisions, dialogue, strategic reasoning | Continuous VRAM and compute use on top of frame rendering | Small-model inference, memory bandwidth |
| AI anti-cheat and behavior analysis | Local or near-edge judgment of player behavior patterns | Resident background computation, raising the power baseline | Lightweight inference, edge computing |
| AI-driven image enhancement | Neural upscaling moving into mainstream frame generation | Dedicated AI core weight keeps rising | Tensor compute units |
In plain shopping language: starting in 2026, the question “is this GPU enough” is expanding from rendering metrics to inference metrics. If the next big game you care about claims to ship with an autonomous NPC system, the traditional raster score in the benchmark table can no longer fully answer its hardware needs.
These three loads are not on equal footing. Image enhancement is the piece vendors already hedge with dedicated AI cores — the part with a clear hardware roadmap. Autonomous NPCs, meanwhile, are the fastest-moving and least standardized: game A’s character model might be lightweight today, and game B might run a far larger model tomorrow. That uncertainty is exactly the part hardest for ordinary players to judge.
The Compute Dividend — and the Catch: Running the Game Isn’t the Same as Running the AI#
Here’s a misalignment many people overlook: games and models eat the same hardware, but they optimize in different directions. Game rendering chases stable per-frame delivery, while continuous inference chases stable VRAM bandwidth and throughput — which is exactly why:
- Midrange cards breeze through traditional games, but if background model inference squeezes VRAM, bandwidth-dependent features like frame generation are the first to “sound the alarm”;
- The premium on big-VRAM models is shifting from “future-proofing” to “AI readiness,” quietly changing the value-retention logic;
- The peak distribution of power draw and heat has changed: full load used to hit in complex scenes; now it may hit during stretches of “dense AI character decision-making.”
The most direct effect on the existing player base: if in-game AI loads ship as optional toggles, frame-chasers will lean toward switching off AI features that add little and buying frames instead — that “settings-page negotiation” will become a standard part of benchmark data.
In other words, the number most worth watching in future GPU reviews may no longer be “how many fps at max settings in game X,” but “with AI features on, how much does fps drop, how much does temperature rise, and does VRAM hold.” Review dimensions shift from single-point performance to a whole-picture judgment of “compute headroom.”
One more easily underestimated variable is the driver’s scheduling policy. When rendering and inference fight over the same chip’s resources, who goes first, how it’s allocated, whether they preempt each other — the driver decides all of it. Bad scheduling might leave your fps nearly intact while AI characters visibly get dumber; or the reverse. So “the AI-era GPU” isn’t just a hardware question — it also depends on whether the software stack can coordinate these two load types well.
How GPU Vendors Respond: AI Goes From Slogan to Line Item#
For the past two GPU generations, vendors mainly marketed “our AI upscaling quality is better.” The 2026 playbook has visibly turned: carry enough AI compute on the card while keeping the cost contained.
| Vendor | Approach | What to Watch |
|---|---|---|
| NVIDIA | Tensor cores plus the ACE ecosystem, end to end on-device | Whether autonomous-NPC inference models can sink down to midrange cards |
| AMD | Scaling up unit counts, pushing VRAM capacity hard | Whether bandwidth performance under inference loads can catch up to rendering metrics |
| Intel | Integrated-graphics matrix units plus low-power edge inference | Whether thin-and-light laptops can run lightweight teammate models locally |
Longer term, vendors face a choice they never had before: AI inference load doesn’t compress into a tidy “medium/high/ultra” expression the way graphics settings do. It’s a dynamic, continuous electricity bill. That means, in product-line planning, “AI performance tiering” will get as concrete as “raster performance tiering.”
For consumers, that’s actually good news — it means AI capability gets polished as a serious spec rather than brushed off as marketing talk. The bad news is it may also open new premium space for “tiering”: the same card with a stronger AI variant may sell for more, even if raster performance improves only a little.
Another variable worth watching is the cloud-versus-edge split. If an in-game AI character’s inference can partly run in the cloud, the local GPU’s pressure shrinks a lot; but cloud inference introduces latency and connectivity costs, which competitive games can’t stomach. How that contradiction gets resolved may well decide the real direction of GPU compute demand over the next few years — whether it keeps piling up in players’ hands or gets moved back to the server.
The Editorial Take#
My personal stance on this trend: bullish on hardware, wait-and-see on the experience:
- Bullish on hardware: AI loads give GPUs fresh differentiation room and give big-VRAM, high-bandwidth models a new reason to be persuasive — a real pull on upgrade cycles.
- Wait-and-see on experience: autonomous NPCs are still mostly “dazzling in the demo, a passenger on live hardware” — genuinely excellent smart character design costs enormous effort, and a badly made AI teammate is less fun than a script.
- For player wallets: as long as AI features stay “optional enhancement” rather than “hardware admission ticket,” owners of older cards don’t need to panic short-term. But the next wave of console replacement three years out could well turn AI inference capability into a hard baseline spec.
The weight of the phrase “optional enhancement” deserves special attention. Historically, a new technology’s move from “optional” to “required” tends to come faster than expected — once developers can assume players have a certain level of inference capability, they’ll confidently build core gameplay on AI characters and stop offering a toggle. At that point, a GPU’s AI capability stops being a bonus item and becomes an entry ticket. That’s the reason I stay cautious long-term while still not wanting players burned by bargain cards.
As a tech editor, what I want to remind you of more is: don’t get carried away by the two letters “AI”. Whether a feature genuinely needs local continuous inference, or is a rendered blob with a new name, is worth a second look. AI that truly changes the experience is the kind you can watch get smarter without noticing it’s running — not one more line of numbers in a benchmark suite.
Wrap-Up#
In 2026, AI’s way into games is shifting from “development assistant” to “player in the game.” Its real impact on hardware isn’t any single revolutionary launch — it’s those three accumulating compute bills: autonomous-NPC inference, background behavior analysis, and image enhancement’s dependence on AI cores. For ordinary players, one takeaway is enough: next time you read a GPU review, don’t fixate on raster fps — also check how the card holds up under sustained inference load.
— That’s all from Zi Xing